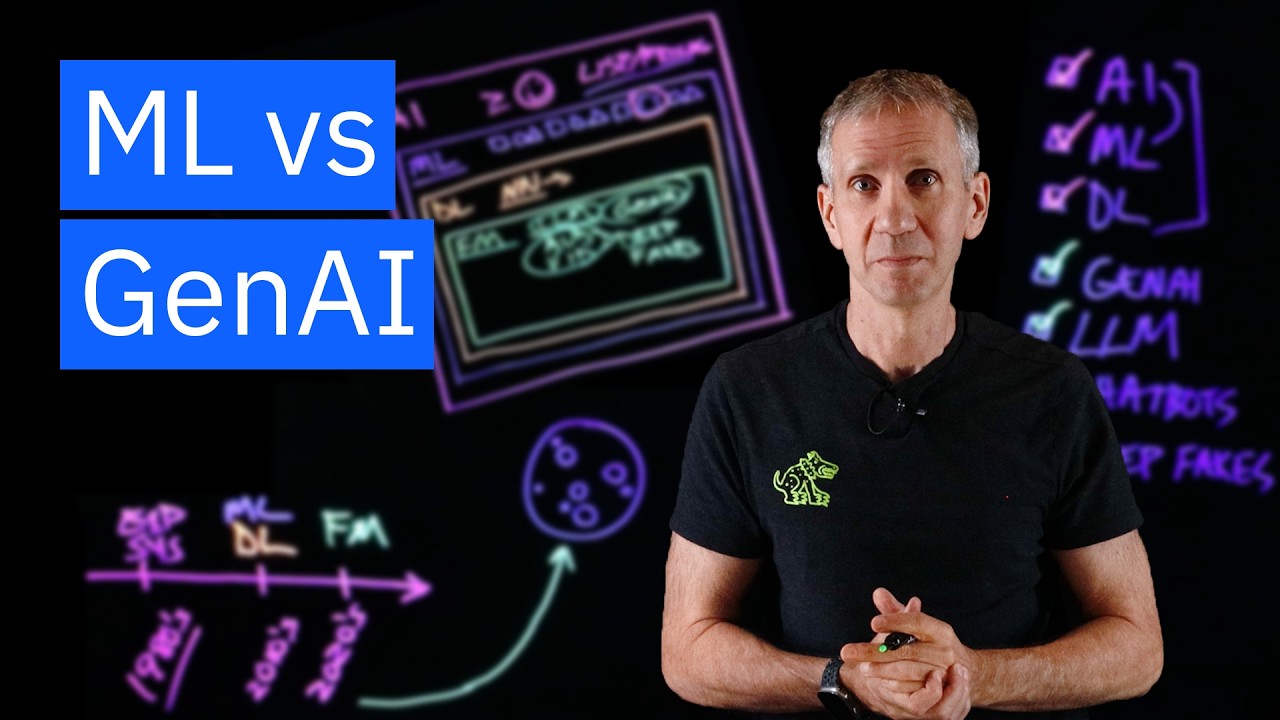
IBM Technology explains large language models like GPT: what they are (foundation models built on data, transformer architecture, and training) and how they learn to predict the next word.
Key Takeaways
- LLMs are foundation models specialized for text, built on transformer architectures.
- They learn by predicting the next word across vast datasets, adjusting billions of parameters.
- Fine-tuning on smaller, specific datasets sharpens performance on particular tasks.
- LLMs have strong business value in customer service automation and software development support.
What the video covers
- GPT (Generative Pre-trained Transformer) is presented as a large language model (LLM) that generates human-like text.
- An LLM is described as an instance of a foundation model applied specifically to text, built from three components: data, architecture, and training.
- Foundation models are pre-trained on large amounts of unlabeled, self-supervised data, learning patterns that yield generalizable and adaptable output.
- The architecture behind GPT is a transformer neural network, which understands each word's context by relating it to every other word in the sentence.
- During training, the model learns to predict the next word and adjusts its internal parameters to reduce prediction error.
- LLMs are trained on large text datasets such as books, articles, and conversations, and are fine-tuned on smaller, task-specific datasets for greater accuracy.
- GPT-3 is cited as pre-trained on about 45 terabytes of data and using 175 billion parameters.
- The video uses a unit comparison: a 1 GB text file holds roughly 178 million words, and training data can reach petabytes.
- Business applications include intelligent customer service chatbots that free human agents for complex issues, and assisting software development by generating and reviewing code.
- The video closes with a question about how many gigabytes are in a petabyte, inviting viewer questions.
Chapters
- 00:00Introduction to GPT and LLMs
- 00:49Foundation models and self-supervised learning
- 02:05What is a large language model?
- 03:04Architecture: transformers and neural networks
- 03:42How training works: predicting the next word
- 04:22Fine-tuning on specific datasets
- 04:37Business applications of LLMs
- 05:05Closing remarks and questions
Full Transcript — Download SRT & Markdown
Speaker A
GPT, or Generative Pre-trained Transformer, is a large language model, or an LLM, that can generate human-like text.
Speaker A
And I've been using GPT in its various forms for years. In this video we are going to number 1, ask "what is an LLM?" Number 2, we are going to describe how they work.
Speaker A
And I've been using GPT in its various forms for years.
Speaker A
Now foundation models are pre-trained on large amounts of unlabeled and self-supervised data, meaning the model learns from patterns in the data in a way that produces generalizable and adaptable output.
Speaker A
In this video, we are going to number one, ask, "What is an LLM?"
Speaker A
I'm talking about things like code. Now, large language models are trained on large datasets of text, such as books, articles and conversations.
Speaker A
Number two, we are going to describe how they work.
Speaker A
We're talking potentially petabytes of data here. So to put that into perspective, a text file that is, let's say, one gigabyte in size, that can store about 178 million words.
Speaker A
And then number three, we're going to ask, "What are the business applications of LLMs?"
Speaker A
Well, it's about 1 million. Yeah, that's truly a lot of text. And LLMs are also among the biggest models when it comes to parameter count.
Speaker A
So let's start with number one, "What is a large language model?"
Speaker A
GPT-3, for example, is pre-trained on a corpus of actually 45 terabytes of data, and it uses 175 billion ML parameters.
Speaker A
Well, a large language model is an instance of something else called a foundation model.
Speaker A
LLM equals three things: data, architecture, and lastly, we can think of it as training.
Speaker A
Now, foundation models are pre-trained on large amounts of unlabeled and self-supervised data, meaning the model learns from patterns in the data in a way that produces generalizable and adaptable output.
Speaker A
As for the architecture, this is a neural network and for GPT that is a transformer.
Speaker A
And large language models are instances of foundation models applied specifically to text and text-like things.
Speaker A
And transformers are designed to understand the context of each word in a sentence by considering it in relation to every other word.
Speaker A
I'm talking about things like code.
Speaker A
And then this architecture is trained on all of this large amount of data. Now, during training, the model learns to predict the next word in a sentence.
Speaker A
Now, large language models are trained on large datasets of text, such as books, articles, and conversations.
Speaker A
But with each iteration, the model adjusts its internal parameters to reduce the difference between its predictions and the actual outcomes.
Speaker A
And look, when we say "large," these models can be tens of gigabytes in size and trained on enormous amounts of text data.
Speaker A
Forget about "bug", it can figure out it's "blue". Now, the model can be fine tuned on a smaller, more specific dataset Here the model refines its understanding to be able to perform this specific task more accurately.
Speaker A
We're talking potentially petabytes of data here.
Speaker A
OK, so how does this all fit into number 3, business applications? Well, for customer service applications, businesses can use LLMs to create intelligent chatbots that can handle a variety of customer queries, freeing up human agents for more complex issues.
Speaker A
So to put that into perspective, a text file that is, let's say, one gigabyte in size, can store about 178 million words.
Speaker A
Hmm, there's an idea. Now, LLMs can even contribute to software development. And they can do that by helping to generate and review code.
Speaker A
A lot of words just in one GB.
Speaker A
And that's why I'm so enamored with large language models. If you have any questions, please drop us a line below.
Speaker A
And how many gigabytes are in a petabyte?
Speaker A
Thanks for watching.
Topics:large language modelGPTtransformerfoundation modelpre-trainingneural networkparametersfine-tuningchatbotsIBM Technology